Cloudflare changed what its Block setting does to mixed-use crawlers on September 15, and added a Training setting it says lets sites refuse AI training while staying in search. Block and “Block on pages with ads” now apply to mixed-use crawlers that serve both search and AI training, including Googlebot, Bingbot and Applebot, so either setting now affects search as well as training. The new setting, Cloudflare’s Disallow AI Training, publishes the applicable no-training preference in robots.txt while those three crawlers stay allowed for search. Anyone who picks Block from now on is picking the setting that stops Googlebot, Bingbot and Applebot too, search included.
What Changed With the Block Setting on September 15
Cloudflare says Block and “Block on pages with ads” “previously did not apply to mixed-use crawlers because blocking them could also affect search discoverability.” That carve-out ends September 15: “Now that we have the new Disallow AI Training setting, Block and ‘Block on pages with ads’ apply to all training crawlers, including mixed-use crawlers.” Most site owners don’t need to act, Cloudflare says: “Nothing, in almost every case. Your current settings carry over on their own.” Anyone who wants mixed-use crawlers gone entirely now has to say so: “Select Block. It will stop Applebot, Bingbot, and Googlebot from reaching your site — search included.”
That departs from the plan in Cloudflare’s July 1 blog post, which said multi-purpose crawlers “such as Googlebot, Applebot, and BingBot will be blocked by customers who have selected to block Training” from September 15. What shipped instead migrates existing Training Block selections to Disallow AI Training, which leaves the three allowed for search, a change from the July plan that Search Engine Journal noted the same day. The crawlers are now caught by an explicit Block or Block on pages with ads, not by a Training opt-out.
Does Cloudflare’s Block Setting Stop Googlebot?
Yes, as of September 15: Cloudflare’s Block setting now stops Googlebot, Bingbot and Applebot, including for search, and “Block on pages with ads” stops them on pages detected to be serving an ad. To stop training while keeping those crawlers for search, Cloudflare points to Disallow AI Training, which publishes the applicable no-training preference in robots.txt and leaves “Accountable” mixed-use crawlers allowed to keep crawling for search. Cloudflare says that preference does not reach Bing through robots.txt yet.
How the Four Crawler Settings Compare
Cloudflare’s Training control now carries four possible values. The table shows how each one treats the three mixed-use crawlers next to every other AI-training crawler.
| Setting | Other AI-training crawlers | Googlebot, Bingbot, Applebot (search) |
|---|---|---|
| Allow | Allowed, unless blocked by another setting or a WAF rule | Allowed for search, unless blocked by another setting or a WAF rule |
| Disallow AI Training | Blocked, including the training-only crawlers run by Amazon, Anthropic, Meta and OpenAI | Allowed for search, if the crawler is designated “Accountable” |
| Block on pages with ads | Blocked on pages detected to be serving an ad | Blocked on pages detected to be serving an ad, search included |
| Block | Blocked entirely | Blocked entirely, search included |
Cloudflare says a robots.txt directive alone “cannot identify who is crawling, determine why they are crawling, or stop a crawler that ignores it.” Its network can, the company says: it publishes the preference, identifies and classifies crawlers, and blocks the ones that ignore it. For the operators themselves, Cloudflare created a designation, “Accountable”: to qualify, an operator must “meet or commit to meeting” four requirements, namely a training opt-out, an AI-summaries opt-out, URL-level visibility into which pages were made available for training along with metrics showing how content appeared in search, and assurance that opting out of AI training will not affect traditional search results. Apple, Google and Microsoft each “combines capabilities available today with time-bound commitments for those still in development,” Cloudflare says. Cloudflare also categorizes the relevant crawlers from Amazon, Anthropic, Meta and OpenAI as Accountable, and says those companies separate their search and training crawlers, so it can block the training crawler without affecting search; under Disallow AI Training, those training-only crawlers are blocked. Cloudflare adds that fewer than 1% of its sites choose to block search bots, while 17% enable some mechanism to block AI training.
What Existing Sites and New Domains Need to Know
For domains that already used the granular controls, Cloudflare says it will “preserve the practical effect of their selections under the new definitions.” Granular Training values of Block or Block on pages with ads become Disallow AI Training; Search and Agent values don’t change. Sites that never configured the granular controls migrate according to their legacy “Block AI Bots” setting: Disabled becomes Search Allow / Training Allow / Agent Allow; Block and Block on pages with ads both become Search Allow / Training Disallow AI Training / Agent Block on pages with ads.
From September 15, customers onboarding a new domain are offered one of two presets, depending on whether the site earns money from advertising, and any setting can be changed during onboarding or at any time afterward: a site without ads is offered Search, Training and Agent all set to Allow; a site monetized with ads is offered Search Allow, Training Disallow AI Training, and Agent Block on pages with ads. Cloudflare’s reasoning: “Ad revenue depends on a human actually seeing the page. Training replaces that visit with an answer; agents fetch the page with nobody there to see the ads.” Both presets set Search to Allow.
Reach Differs by Operator: Google, Apple and Bing
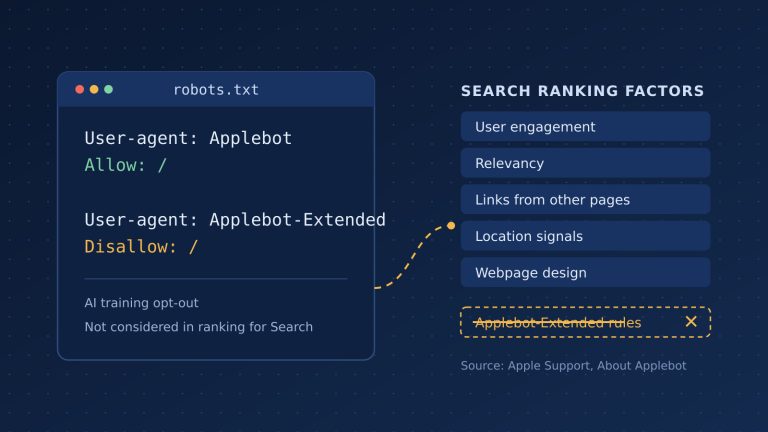
Disallow AI Training isn’t one network-wide switch. For Google and Apple it becomes a robots.txt request; for Bing, it doesn’t reach the crawler yet.
| Operator | Training opt-out this setting relies on | AI-answer control today | What’s pending |
|---|---|---|---|
| Disallow rule for Google-Extended | Search generative AI control in Search Console (AI Overviews, AI Mode, generative AI features in Discover) | URL-level transparency tools tied to Google-Extended, which Cloudflare says Google expects to launch “in the weeks to come” | |
| Apple | Disallow rule for Applebot-Extended | nosnippet meta tag | A URL-level inspection tool; Cloudflare says Apple shared “details of their in-progress solution for next year” |
| Microsoft (Bing) | None yet through Cloudflare’s setting | NOARCHIVE meta tag; Bing’s 2023 post says NOARCHIVE content is not included in Bing Chat answers | Robots.txt support for a no-training preference, which Cloudflare says is “targeted for early 2027” |
Google’s own crawler documentation says Google-Extended “does not impact a site’s inclusion in Google Search nor is it used as a ranking signal in Google Search”; a site’s inclusion in AI Overviews, AI Mode and Discover’s generative features is managed instead through the Search AI controls setting Google says now reaches all websites worldwide, which Google’s help page calls the Search generative AI control. Apple has already put in writing that Applebot-Extended carries no Search ranking cost. Bing is the gap: Cloudflare says site owners who want to opt out of training in Bing today can use the NOARCHIVE meta tag Bing described in 2023, plus Bing’s Block URLs or Content Removal tool. Bing’s post says NOARCHIVE content “will not be included in Bing Chat answers, not be linked to in the answers,” and that Bing “will not use the content for training Microsoft’s generative AI foundation models.” The same post adds: “If content has both NOCACHE and NOARCHIVE tags, we will treat it as NOCACHE,” and NOCACHE content “may be included in Bing Chat answers.”
Checking Your Own Settings
Bot Preference Sync is the Cloudflare feature that publishes the no-training preference into a site’s robots.txt file. Anyone maintaining robots.txt by hand, on Cloudflare or elsewhere, can build and syntax-check robots.txt rules for Google-Extended and Applebot-Extended groups instead of editing the file blind. Cloudflare’s next step is AI summaries: a stated goal, not yet a launch, to let a site owner control how much content goes into summaries, set once on Cloudflare “rather than with each operator separately,” by early next year.
For Googlebot, Bingbot and Applebot, Disallow AI Training is a robots.txt request that reaches Google and Apple today, does not reach Bing yet, and doesn’t decide whether a page appears in AI Overviews or AI Mode. Block used to skip the three mixed-use crawlers; from September 15 it stops them, search included.